プロンプト
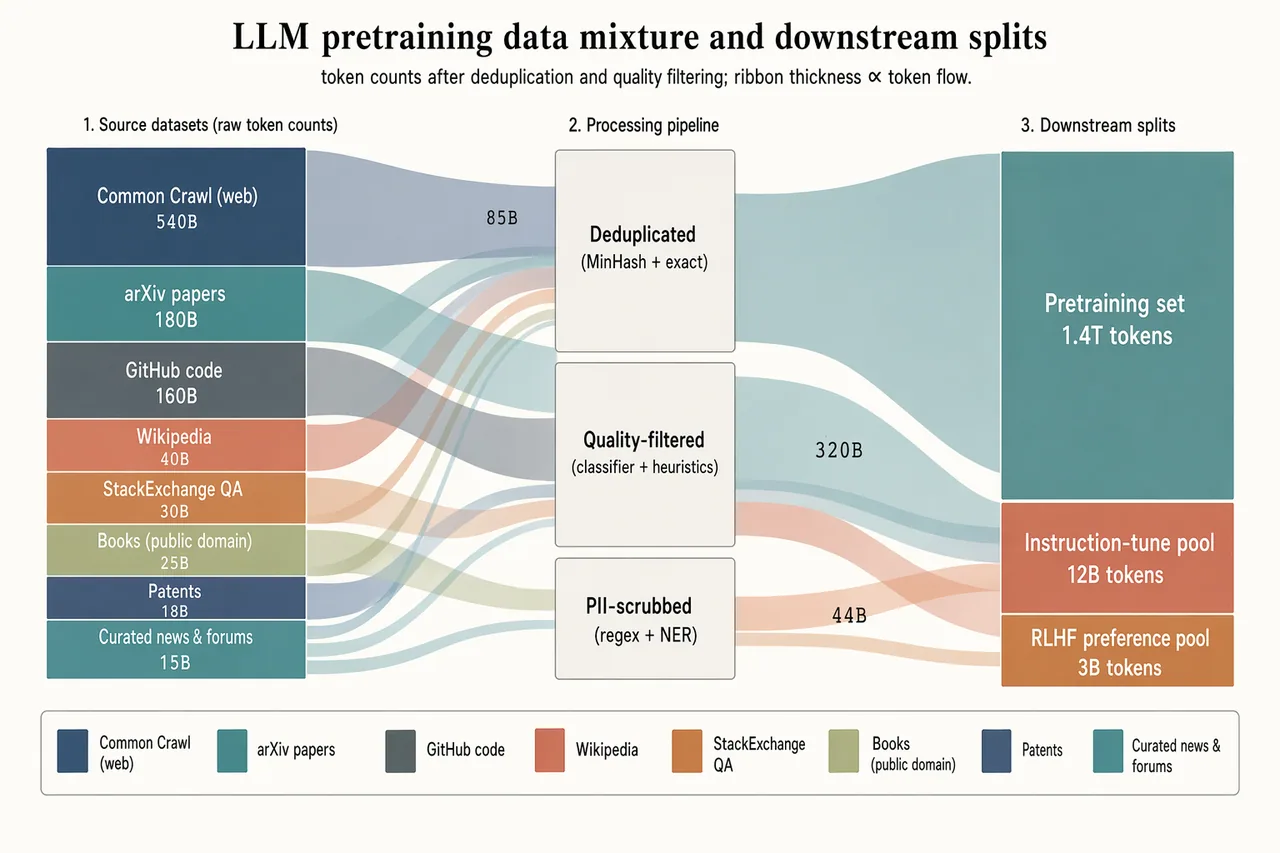
Landscape 16:9 sankey diagram of a pretraining data mixture, three stages with translucent colored ribbons.

LEFT (8 source blocks, heights proportional to tokens): "Common Crawl (web) 540B" (muted navy, largest), "arXiv papers 180B" (dusty teal), "GitHub code 160B" (slate gray), "Wikipedia 40B" (soft terracotta), "StackExchange QA 30B" (warm copper), "Books (public domain) 25B" (pale olive), "Patents 18B" (pale navy), "Curated news & forums 15B" (dusty teal).

MIDDLE (3 processing blocks, stacked): "Deduplicated (MinHash + exact)", "Quality-filtered (classifier + heuristics)", "PII-scrubbed (regex + NER)".

RIGHT (3 final splits): "Pretraining set 1.4T tokens" (largest), "Instruction-tune pool 12B tokens", "RLHF preference pool 3B tokens".

Flow ribbons inherit source color with mid-labels showing token counts ("85B", "320B", "44B"). Legend strip at bottom.

Title: "LLM pretraining data mixture and downstream splits". Subtitle: "token counts after deduplication and quality filtering; ribbon thickness ∝ token flow."