프롬프트
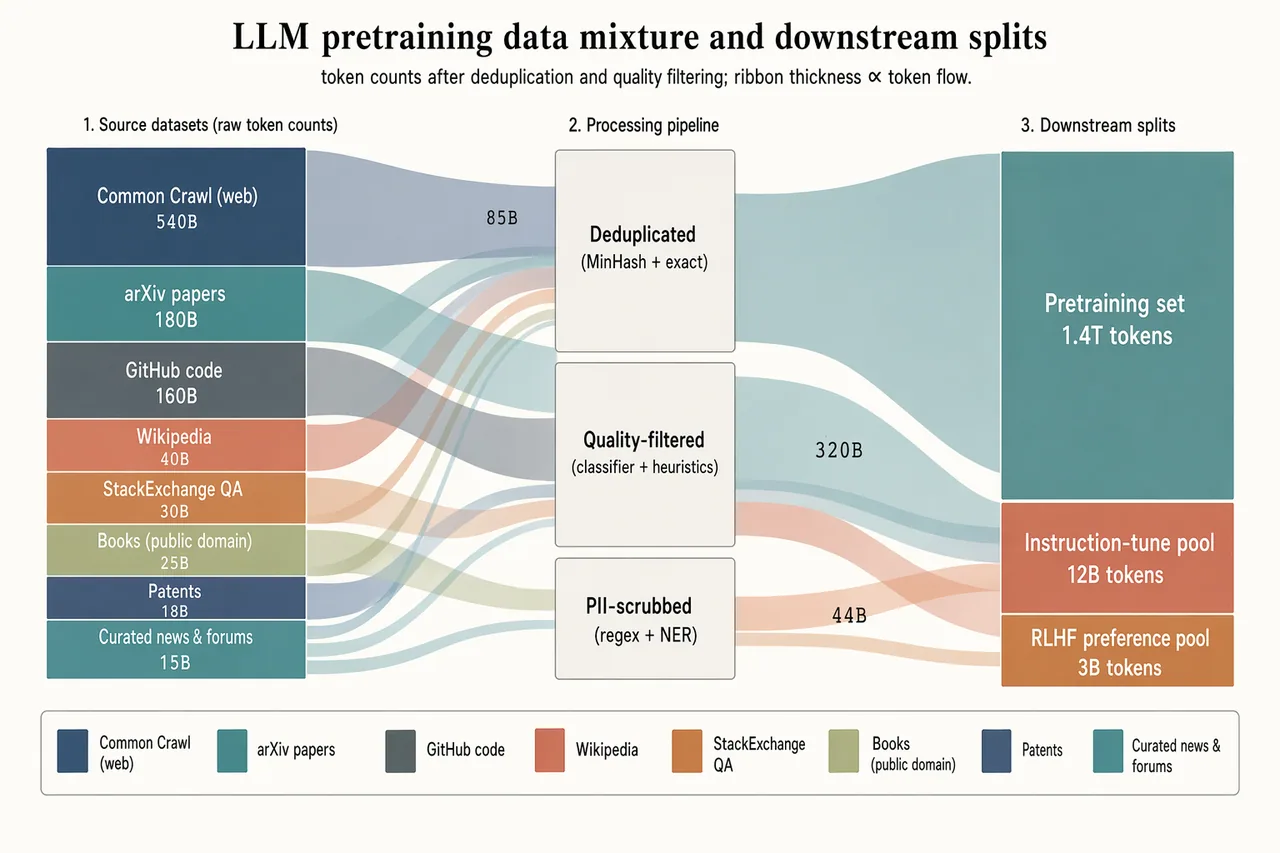
Landscape 16:9 sankey diagram of a pretraining data mixture, three stages with translucent colored ribbons.

LEFT (8 source blocks, heights proportional to tokens): "Common Crawl (web) 540B" (muted navy, largest), "arXiv papers 180B" (dusty teal), "GitHub code 160B" (slate gray), "Wikipedia 40B" (soft terracotta), "StackExchange QA 30B" (warm copper), "Books (public domain) 25B" (pale olive), "Patents 18B" (pale navy), "Curated news & forums 15B" (dusty teal).

MIDDLE (3 processing blocks, stacked): "Deduplicated (MinHash + exact)", "Quality-filtered (classifier + heuristics)", "PII-scrubbed (regex + NER)".

RIGHT (3 final splits): "Pretraining set 1.4T tokens" (largest), "Instruction-tune pool 12B tokens", "RLHF preference pool 3B tokens".

Flow ribbons inherit source color with mid-labels showing token counts ("85B", "320B", "44B"). Legend strip at bottom.

Title: "LLM pretraining data mixture and downstream splits". Subtitle: "token counts after deduplication and quality filtering; ribbon thickness ∝ token flow."
한국어 번역
사전학습 데이터 혼합의 가로 16:9 생키 다이어그램, 반투명 색상 리본이 있는 세 단계.

왼쪽(8개 소스 블록, 높이는 토큰에 비례): "Common Crawl (web) 540B"(차분한 네이비, 가장 큼), "arXiv papers 180B"(더스티 틸), "GitHub code 160B"(슬레이트 그레이), "Wikipedia 40B"(부드러운 테라코타), "StackExchange QA 30B"(따뜻한 구리색), "Books (public domain) 25B"(옅은 올리브), "Patents 18B"(옅은 네이비), "Curated news & forums 15B"(더스티 틸).

가운데(3개 처리 블록, 적층): "Deduplicated (MinHash + exact)", "Quality-filtered (classifier + heuristics)", "PII-scrubbed (regex + NER)".

오른쪽(3개 최종 분할): "Pretraining set 1.4T tokens"(가장 큼), "Instruction-tune pool 12B tokens", "RLHF preference pool 3B tokens".

흐름 리본은 소스 색상을 상속하고 중간 레이블에 토큰 수 표시("85B", "320B", "44B"). 하단에 범례 띠.

제목: "LLM 사전학습 데이터 혼합 및 하위 분할". 부제: "중복 제거 및 품질 필터링 후의 토큰 수; 리본 두께 ∝ 토큰 흐름."